Today, artificial intelligence has become extremely reliant on data. Recommendations, fraud prevention, healthcare analysis, and generative artificial intelligence are all based on the collection of information and its further use for training, forecasting, and decision-making. This growing reliance on data makes AI and data privacy an important consideration for organizations and individuals.
However, there comes a vital question.
How many personal data points are required to facilitate AI innovation?
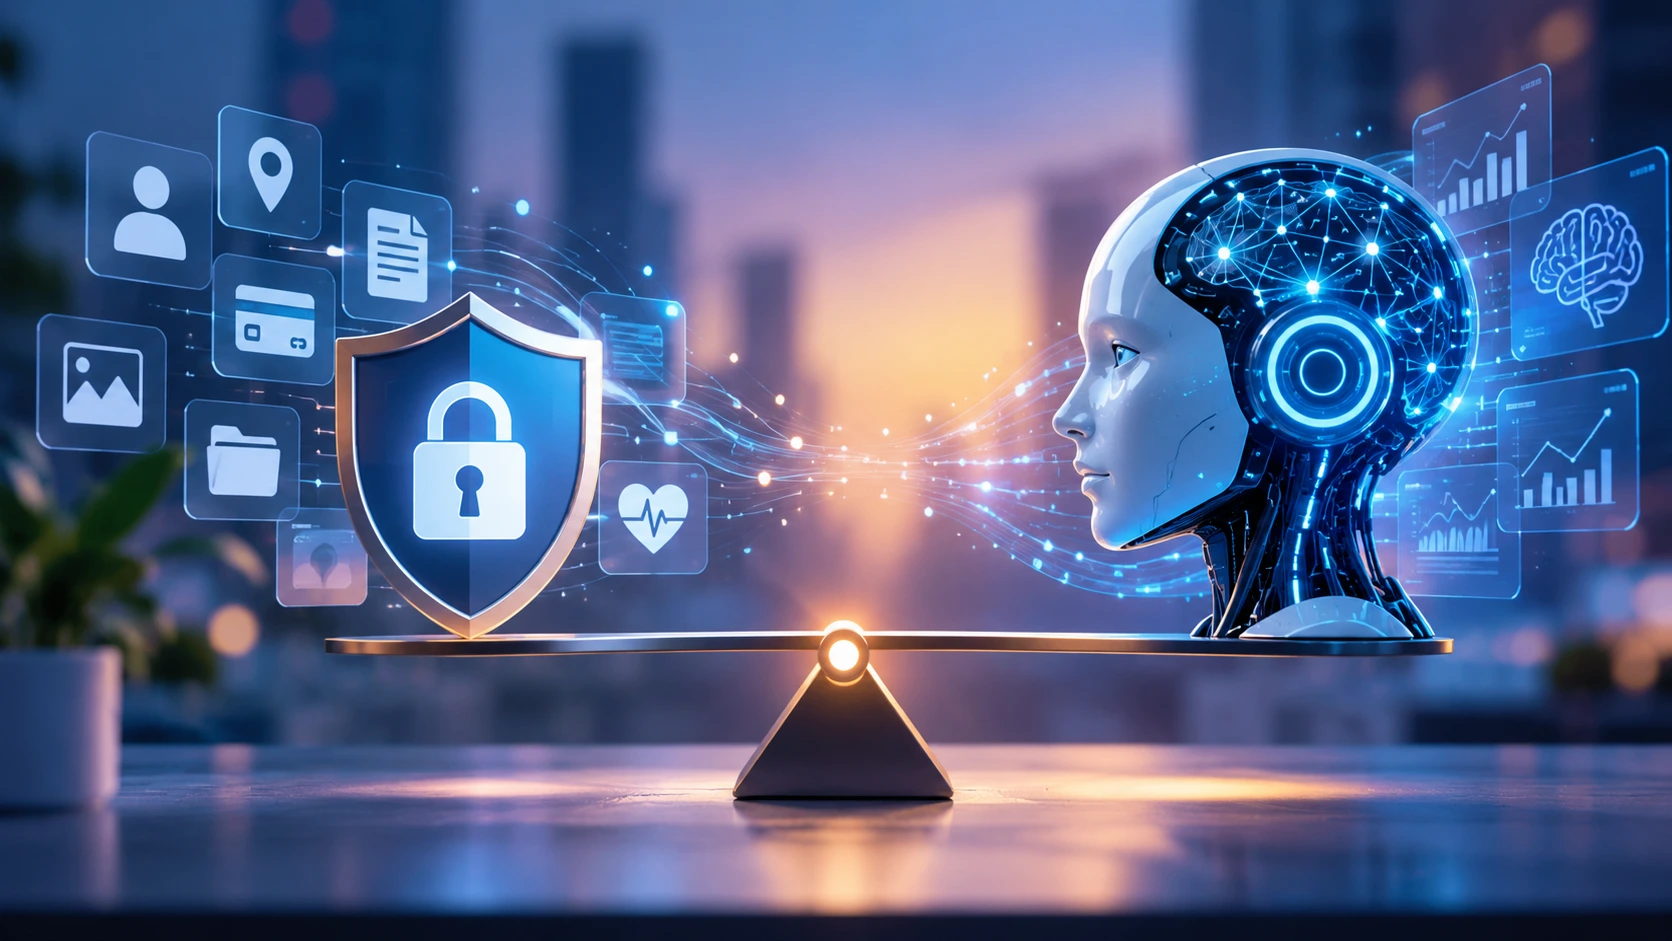
As more data is collected by different organizations and innovative artificial intelligence is developed, therefore, there comes a necessity to think about a balance between data privacy and technological innovations.
Therefore, the objective here shouldn’t be to choose one of the two but rather look for ways to combine data privacy and innovation to protect people from harm.
What Is Data Privacy?
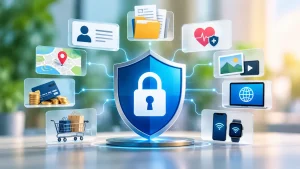
Data privacy relates to how the personal data of an individual is collected, stored, processed, shared, and protected.
Personal data may include:
- Personal names and contacts
- Location data
- Financial information
- Information about online activity
- Purchase history
- Images and videos
- Information related to health
- Device and behaviour data
The growing ability of AI systems to analyse huge datasets complicates the protection of such data.
Even a seemingly innocent set of data becomes sensitive information if it is used in conjunction with other data sets.
Why Does AI Need So Much Data?
Machine learning algorithms learn from data.
For instance, a recommendation engine can take into account:
- Customer views on the products
- Products purchased by the customer
- Number of visits to the site
- Products ignored
- History of searches
The larger the volume and quality of the data, the more patterns the algorithm will be able to see.
This is one of the reasons why companies strive for access to big data sets.
But having a lot of data does not necessarily lead to a good artificial intelligence model.
Bad, irrelevant, biased, or poorly obtained data might produce an inefficient AI system.
Privacy Risks
That same data that is needed for improving the AI can become a source of privacy violations.
Consider a company collecting millions of customer interactions to train their AI recommendation system.
It might be known what:
- Consumers purchase
- They shop from
- When they do shopping
- They are looking for
- Their devices of choice
- What content interacts with
In case there is poor security around such information or any other use beyond its initial scope, people will not have full control over their personal information.
There are different kinds of threats involved.
1. Unauthorized access
There could be a data breach, exposing sensitive information related to many, if not millions of people.
2. Overcollection of information
Information is collected just because it might turn out useful sometime later.
That leads to unnecessary privacy issues.
3. Inadequate transparency
People might be unaware about how their information is used to operate and train AI algorithms.
4. Re-identification
In cases where the identifying information is stripped, people might be still re-identified using datasets.
5. Algorithmic profiling
Algorithmic analysis allows creating highly detailed individual profiles, based on their behaviour, preferences and interaction.
Does Privacy Inhibit Innovation in AI?
A prevalent concern is that the need for privacy makes innovation in AI technology difficult.
Organizations might not have enough data to train and test algorithms since they would not be able to collect and process any personal data.
Furthermore, there could be other expenses linked to:
- Data management
- Security
- Compliance
- Anonymization
- Access control
- Monitoring
- Privacy-preserving technologies
However, seeing privacy merely as an inhibitor is a misconception.
Privacy can actually promote organizations in the construction of sound data practices and trustworthy AI systems.
The aim should not be:
“Collect as much data as possible.”
Rather, it should be:
“Collect the least amount of data required to accomplish the desired goal.”
Is AI Innovation Possible Without Exposing Personal Information?
Absolutely.
There are now a number of ways for data scientists to mitigate privacy concerns while letting organizations innovate in AI technology.
Data Anonymization
Information that can identify personally identifiable information may be stripped or altered prior to the data being analyzed.
However, care must be taken when anonymizing data as apparently anonymous data can be de-anonymized in some cases.
Data Minimization
Companies can restrict the data they collect and use to only that which is necessary for a specific purpose.
For instance, a data analytics model may need a consumer’s age group instead of their actual birth date.
Synthetic Data
Synthetic data refers to artificial data that aims at reproducing useful statistics without replicating real-life individuals.
It can be helpful for:
- Testing
- Modeling
- Software Development
- Research
- Training some AI models
Synthetic data doesn’t make data any less private but can decrease the reliance on sensitive real-world datasets.
Federated Learning
Federated learning enables machine learning models to be trained using data from several devices or companies while avoiding the need to transfer all the data to a central server.
Instead of moving the data to the model, the model is moved to the data. As a result, this approach can be especially helpful when data is scattered across many different locations.
Differential Privacy
This is the practice of adding carefully controlled statistical noise to the dataset or analysis results.
The aim is to make it hard to figure out if information from any particular individual was used in the result.
Role of Data Scientists
While protecting data privacy may seem like a job for legal and cybersecurity teams, data scientists also have their responsibilities in this area.
A data scientist should think about data privacy at every stage of the machine learning workflow:
Data Collection → Data Storage → Data Preparation → Model Development → Evaluation → Deployment → Monitoring
At each stage there should be questions asked such as:
- Do we really need this data?
- Was the data gathered properly?
- Who needs access to the data?
- Can people be identified?
- Is sensitive data being used when it is not needed?
- Can the model be revealing private data?
- Are we holding the data for too long?
These questions help shift privacy from being an add-on task to an integral part of data science. As the role of data scientists continues to evolve, understanding how the field is moving from traditional machine learning to AI-powered data science is becoming increasingly important.
Privacy by Design
One such idea is called Privacy by Design.
Rather than building an AI system first and then trying to bolt on privacy protections, privacy must be taken into account right from the outset.
Take for example the design of a customer analytics system: Developers can think about all of the following questions from the very start:
- What information do we need?
- What information must never be gathered?
- How long should information be kept?
- Who should have access to it?
- How can we protect sensitive information?
- How can we inform users?
Doing so might mitigate privacy risks while building a trusted system.
Innovation vs. Privacy? Wrong Question
The discussion is often framed in the following way:
Privacy OR Innovation
A much better discussion would go something like this:
Privacy AND Innovation
Companies can innovate while respecting the rights of people by making investments in privacy technologies, responsible data governance, cybersecurity infrastructure, and transparent use of AI technology. Furthermore, privacy can be a competitive advantage. Therefore, people are more likely to trust companies that are open about their data handling and show that they respect the privacy of people.
What Will the Future Hold?
The future of AI will certainly involve a lot more privacy-preserving AI.
However, technologies like federated learning, differential privacy, synthetic data, secure computation, and improved access controls can assist organizations in tapping into the potential of their data while exposing personal information as little as possible.
On the contrary, the rules and regulations in the sphere of data protection and the needs of society are expected to influence the further development of AI technologies.
This means that future data scientists will be required to possess not only skills in programming languages, algorithms, statistics, and machine learning, but also data governance, data security, ethics, and privacy.
Conclusion
As the innovation in AI is dependent on data, it does not mean that the companies should think of personal data of their customers as an inexhaustible source.
The main problem here is to achieve balance between the application of data for creating value and protecting those people who provide this data.
The responsible use of AI technology is not about stopping the innovation process.
This is about considering whether
Can we construct this framework without putting people at unnecessary risk?
Future Data Science shouldn’t involve gathering as much data as possible.
It should be about creating maximum value out of data and doing so in a manner that does the least harm possible.
And maybe the most essential thing that next-generation AI needs to stand by is the following:
Good AI won’t just be powerful. It will also be trustworthy.